|
My research focuses on multimodal learning, with particular emphasis on understanding the internal mechanisms of heterogeneous modality integration and enhancing the external perception and cognition of multimodal intelligence. I earned my Ph.D. in Artificial Intelligence from Renmin University of China (RUC) in June 2026, under the supervision of Prof. Di Hu. Before that, I received my B.E. in Computer Science and Technology from University of Electronic Science and Technology of China (UESTC) in June 2021. Grateful to everyone who supported me along the way. If you're interested in working with me, please feel free to reach out! |
Lecturer |
|
My research focuses on how multimodal systems learn from, perceive, and reason over heterogeneous signals such as vision, audio, and language. My work spans two complementary directions: External Perception & Cognition. Advancing the perception and cognition ability of multimodal intelligence to support coherent understanding, reasoning, and interaction across complex physical and digital environments. Internal Learning Dynamics. Leveraging cognitive neuroscience and mathematical tools to investigate the coordination, integration, and interaction of heterogeneous multimodal information within unified learning systems. 
|
|
|
|
 HIGHLIGHT |
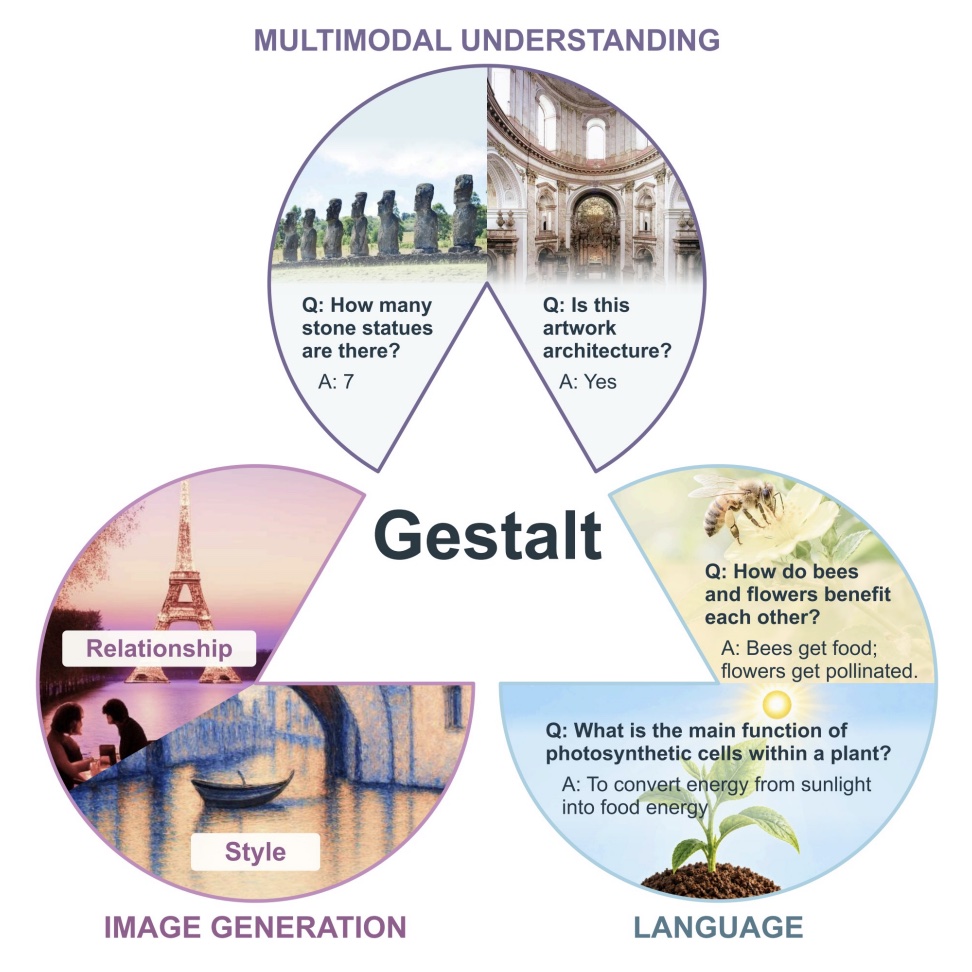
Zequn Yang*, Yu Miao*, Haotian Ni*, Ziheng Chen*, Chengxiang Huang*, Dongzhan Zhou, Kai Chen, Qi Zhang, Ji-Rong Wen, Yake Wei‡, Di Hu‡ (‡: Team leader) Preprint, 2026 Project Page A new paradigm of large multimodal model built around multimodal interplay. |
 HIGHLIGHT |
Yake Wei, Yu Miao, Dongzhan Zhou, Di Hu NeurIPS, 2025 (Oral Presentation, 1.46% of accepted papers) Project page A new PEFT pipeline for MLLMs, ensuring both uni-/cross-modal adaptation. |
 HIGHLIGHT |
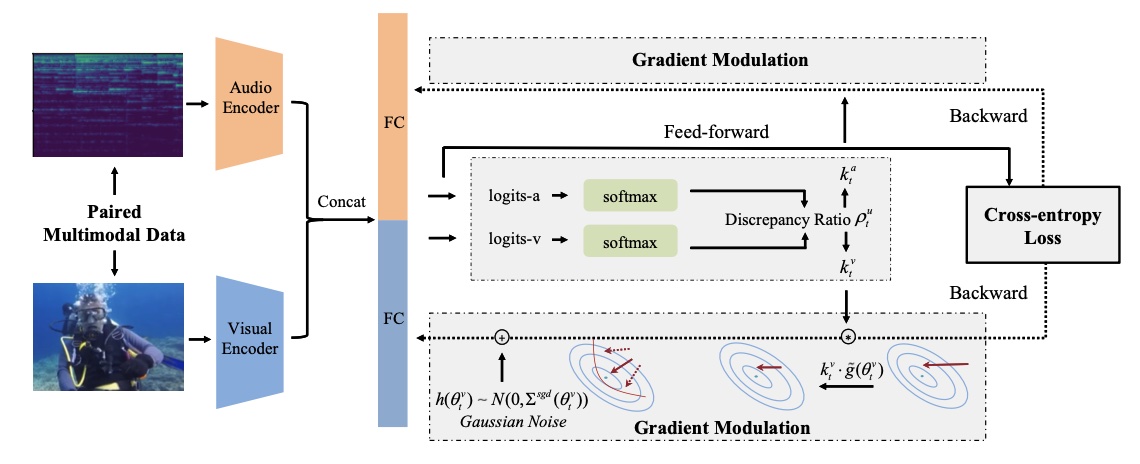
Xiaokang Peng*, Yake Wei*, Andong Deng, Dong Wang, Di Hu (∗: equal contribution) CVPR, 2022 (Oral Presentation) arXiv / code Alleviate imbalance in multimodal learning via dynamic gradient modulation. |
|
2026 — Wu Yuzhang Scholarship (RUC’s highest student honor; awarded to 10 graduates annually). 2026 — Outstanding Graduate of Renmin University of China. 2026 — Selected to participate in the CVPR 2026 Doctoral Consortium. 2024 — Baidu Scholarship (10 PhD students worldwide). 2024 — National Scholarship for PhD Students (China’s highest student honor). 2021 — Outstanding Graduate of Sichuan Province (highest graduate honor awarded by Sichuan Province). 2021 — Outstanding Graduate of the University of Electronic Science and Technology of China. Student Travel Award · NeurIPS 2025 · CVPR 2024 |
|
|
|
|
HIGHLIGHT
|
Zequn Yang*, Yu Miao*, Haotian Ni*, Ziheng Chen*, Chengxiang Huang*, Dongzhan Zhou, Kai Chen, Qi Zhang, Ji-Rong Wen, Yake Wei‡, Di Hu‡ (‡: Team leader) Preprint, 2026 Project Page A new paradigm of large multimodal model built around multimodal interplay. |

|
Yake Wei, Yuan Wang, Fengyun Rao, Jing Lyu, Di Hu Preprint, 2026 arXiv Use pixel grounding to enhance MLLM's fine-grained visual perception. |
|
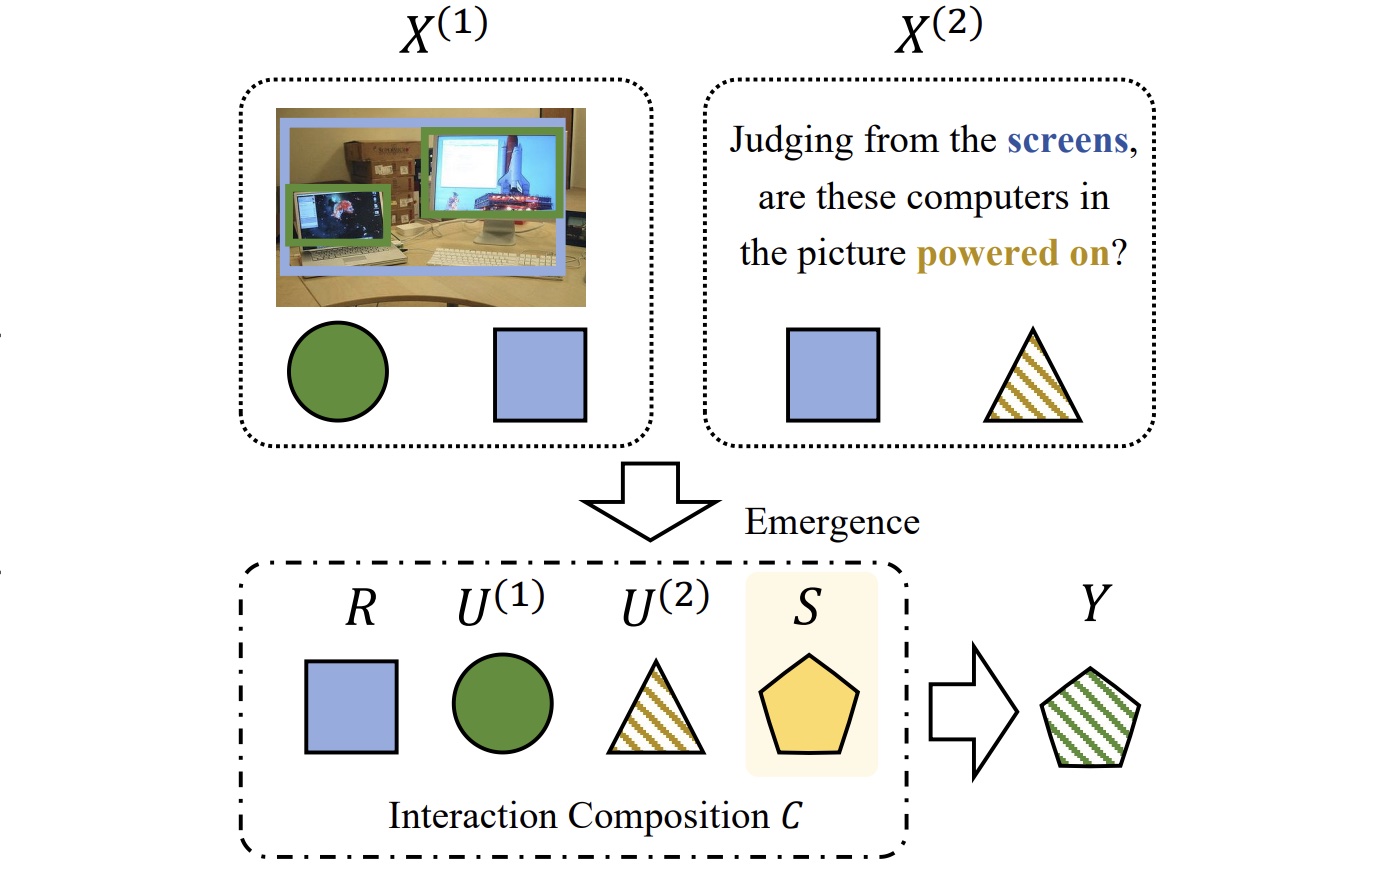
Zequn Yang, Yake Wei, Haotian Ni, Zhihao Xu, Di Hu CVPR, 2026 arXiv Distinguish and strengthen multimodal interactions within the data. |
|
HIGHLIGHT
|
Yake Wei, Yu Miao, Dongzhan Zhou, Di Hu NeurIPS, 2025 (Oral Presentation, 1.46% of accepted papers) Project page A new PEFT pipeline for MLLMs, ensuring both uni-/cross-modal adaptation. |

|
Haotian Ni, Yake Wei, Hang Liu, Gong Chen, Chong Peng, Hao Lin, Di Hu ICML, 2025 arXiv / code Rebalance and revive cooperation between modalities in Transformer. |
|
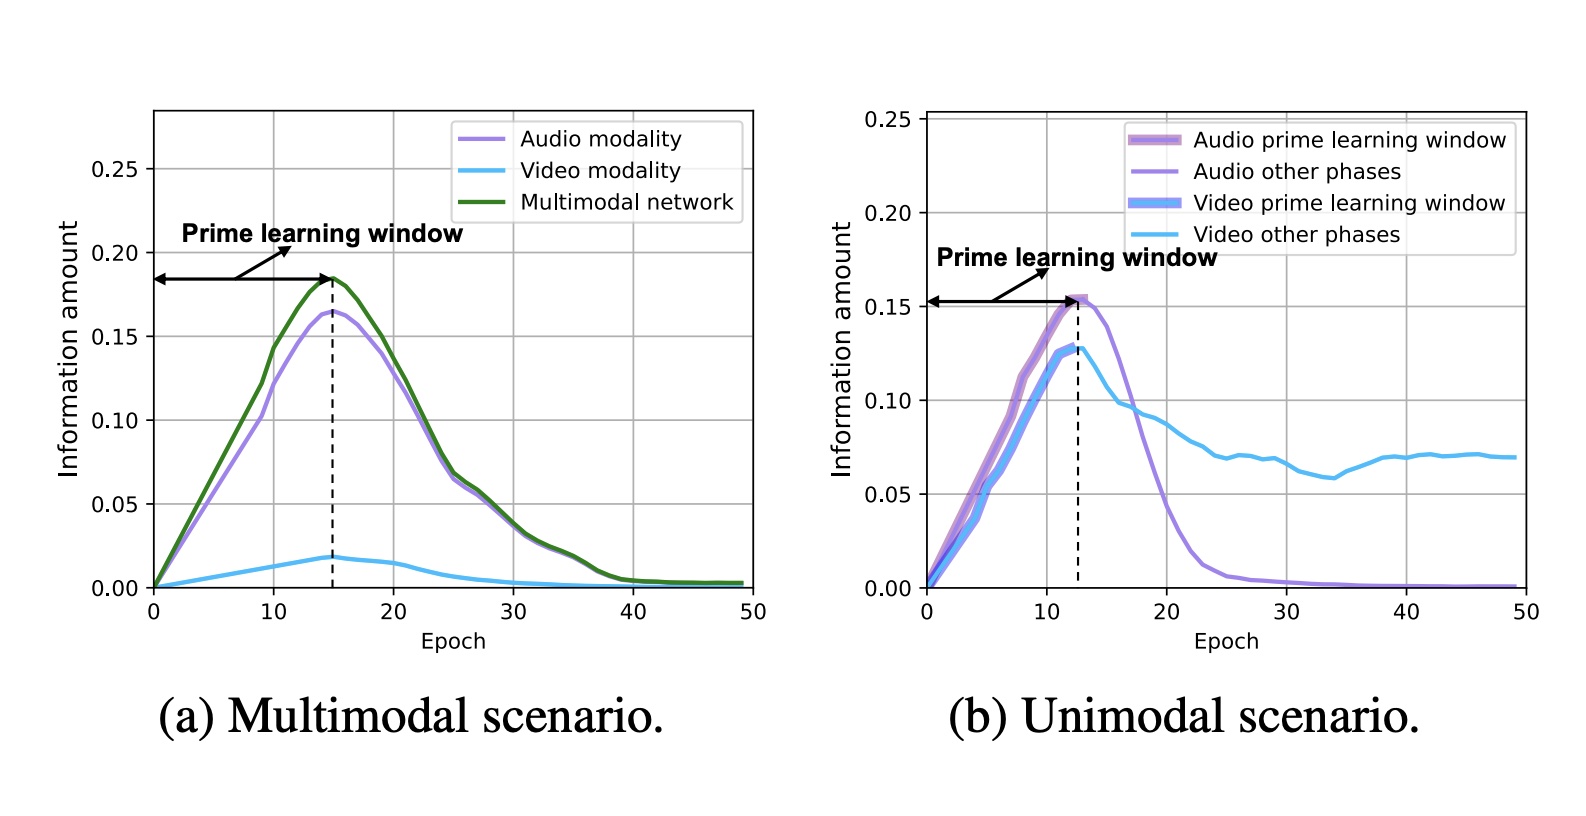
Chengxiang Huang*, Yake Wei*, Zequn Yang, Di Hu CVPR, 2025 arXiv / code Analyze and modulate information acquisition process during multimodal training. |
|
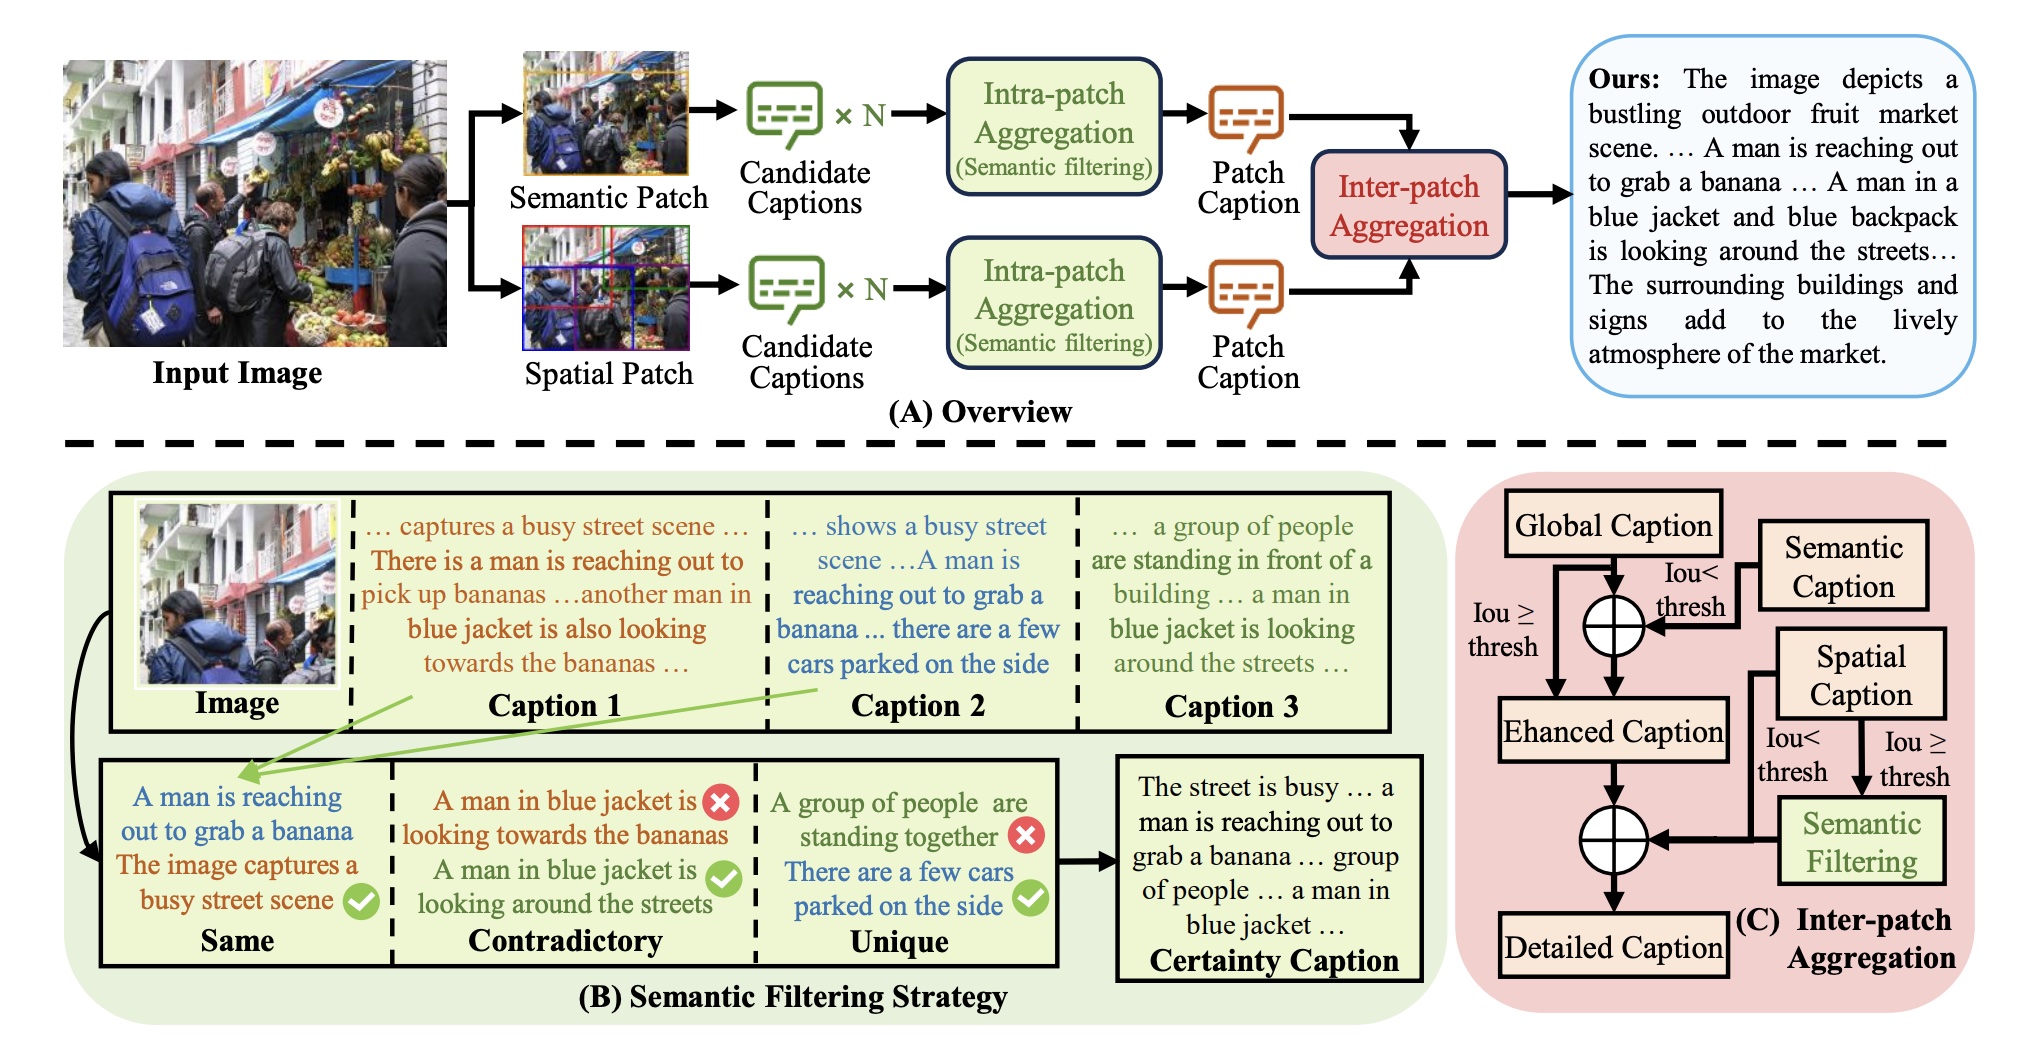
Ruotian Peng, Haiying He, Yake Wei, Yandong Wen, Di Hu CVPR, 2025 arXiv / code Generate high-quality image caption by divide-then-aggregate strategy. |
|
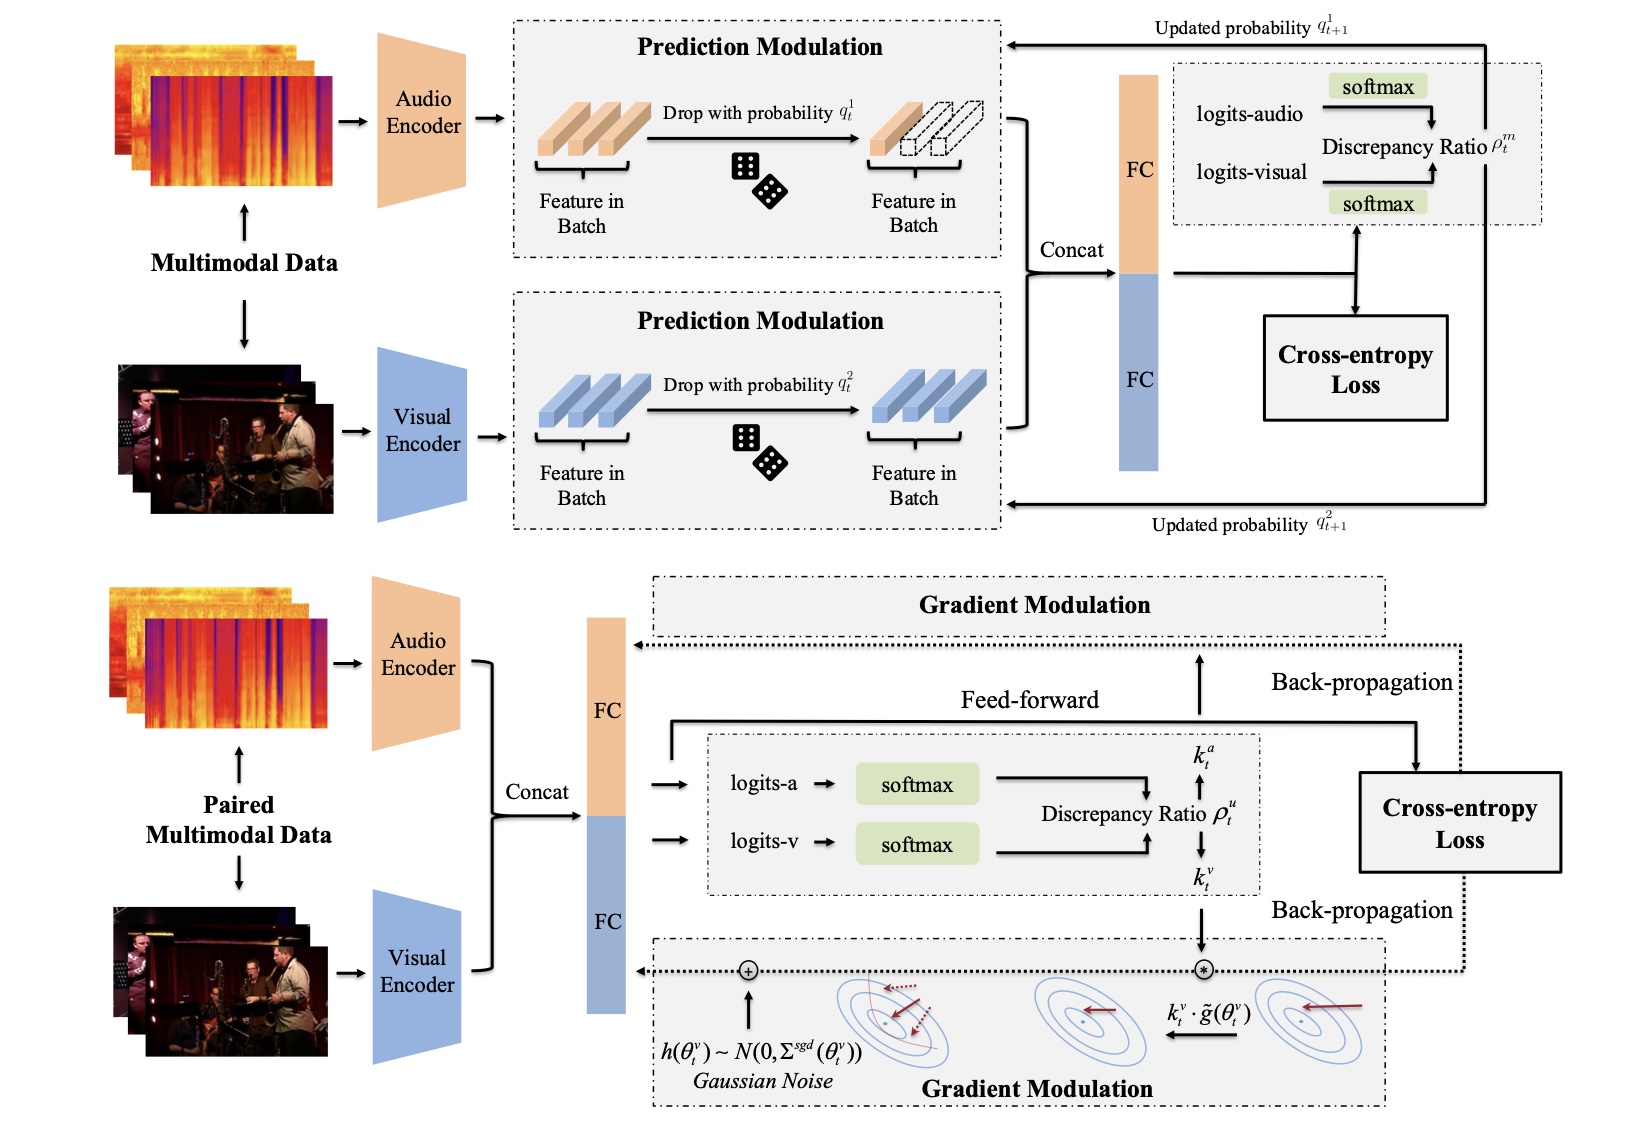
Yake Wei, Di Hu, Henghui Du, Ji-Rong Wen P.S. Thanks the valuable help from Zequn Yang T-PAMI, 2024 arXiv / code Analyze and modulate imbalanced unimodal learning from both feed-forward and back-propagation stage. |
|
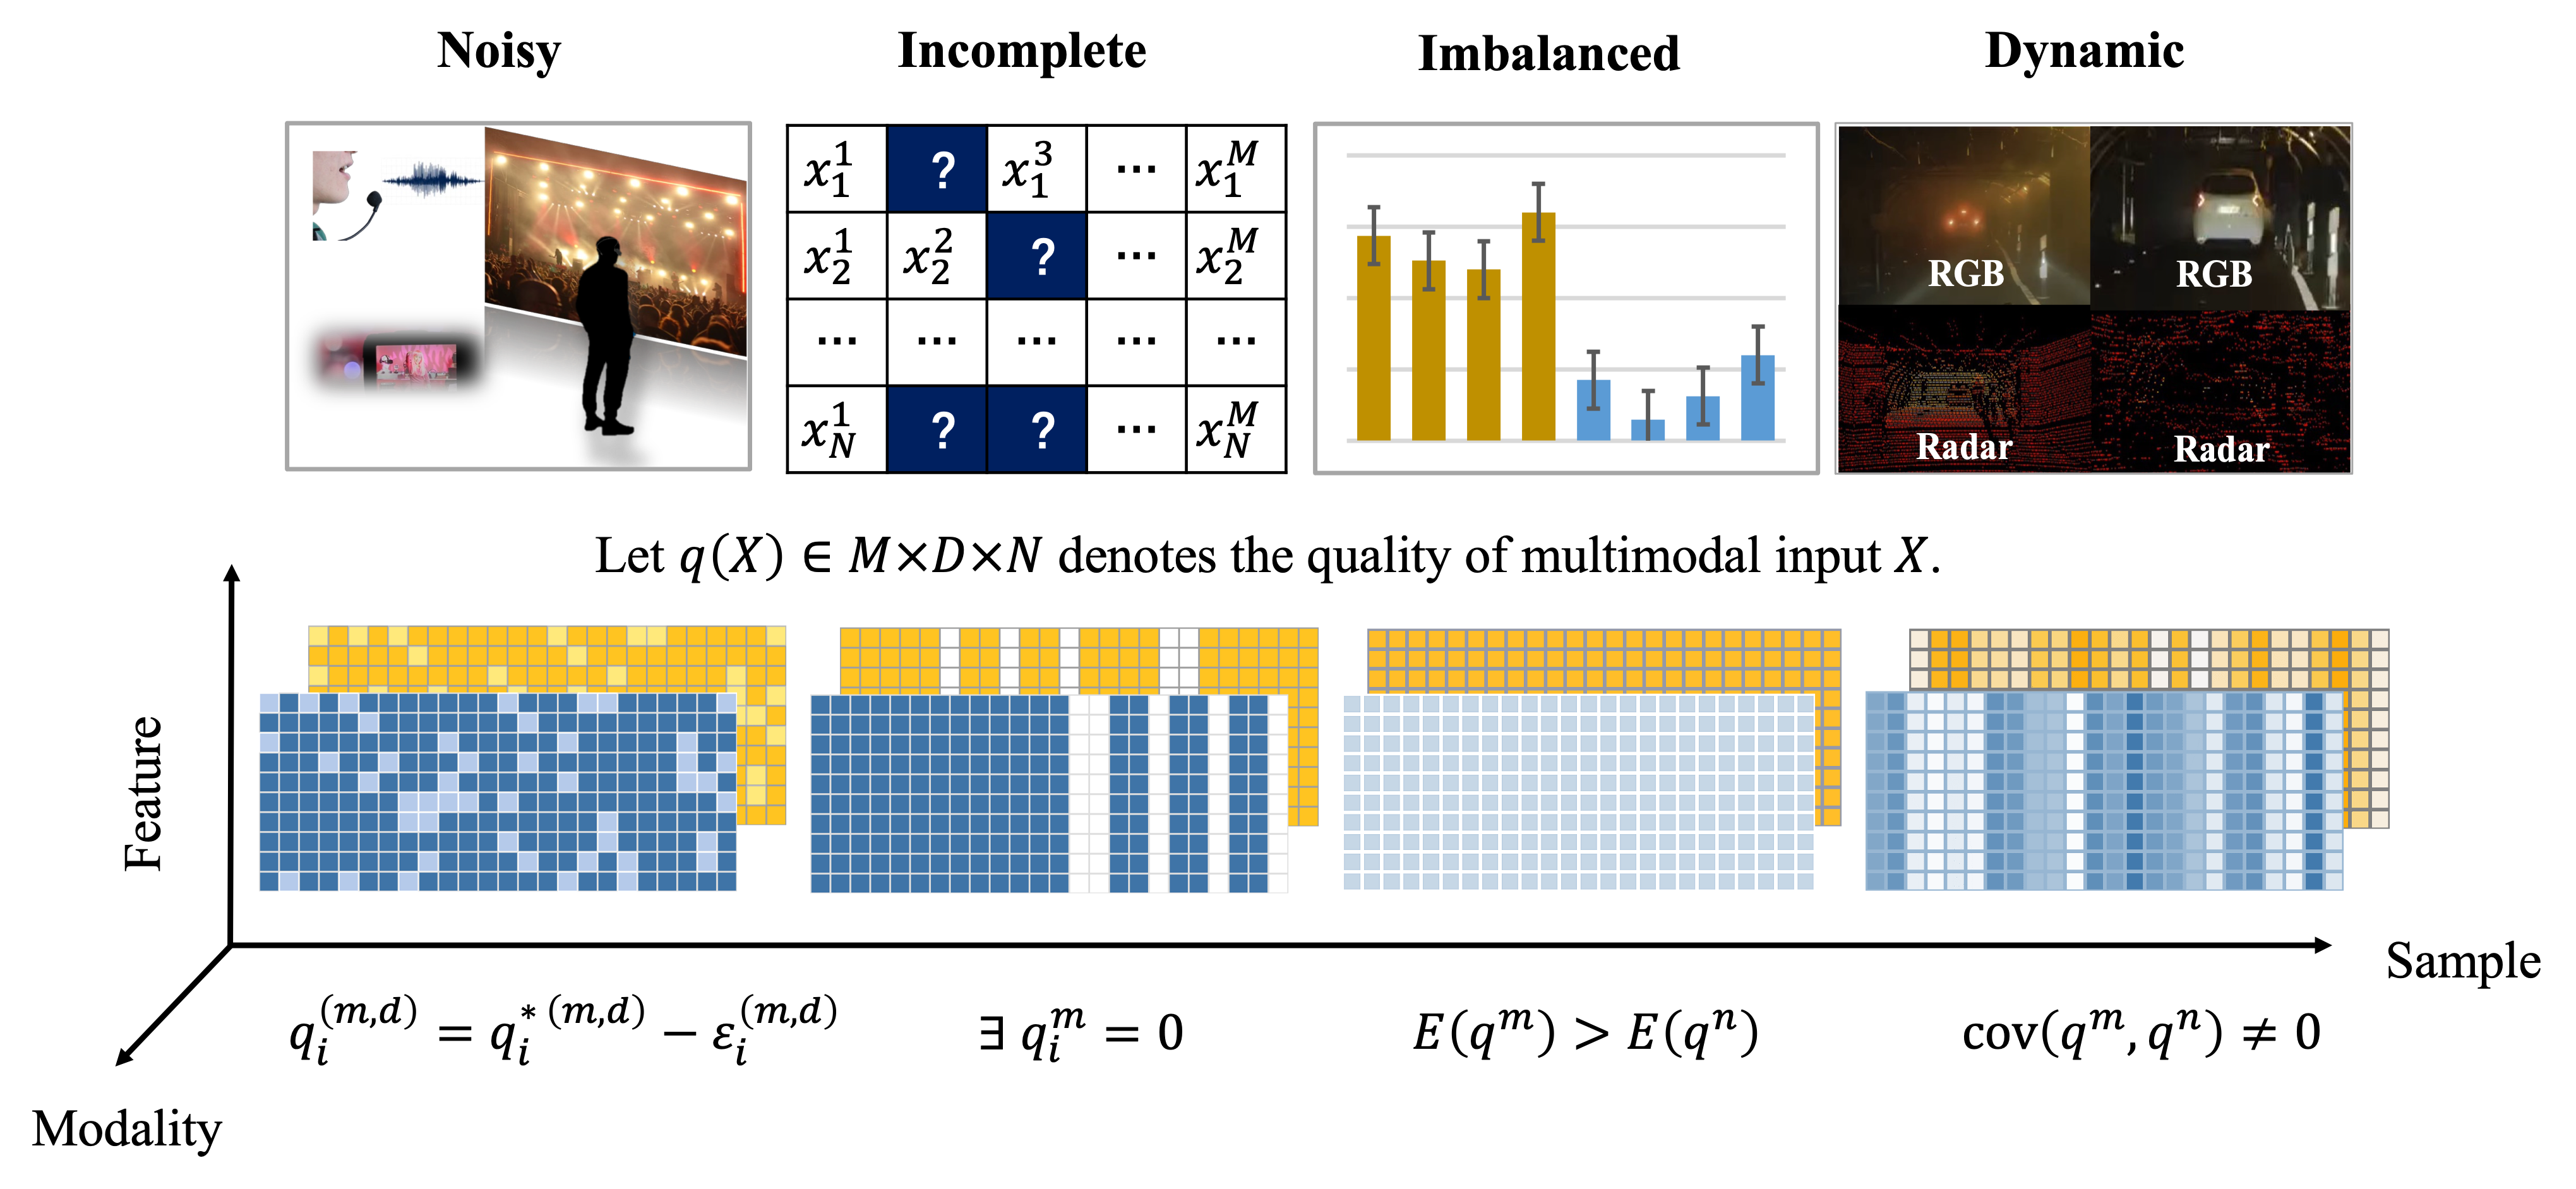
Qingyang Zhang, Yake Wei, Zongbo Han, Huazhu Fu, Xi Peng, Cheng Deng, Qinghua Hu, Cai Xu, Jie Wen, Di Hu, Changqing Zhang Information Fusion, 2026 arXiv / awesome list A systematic survey about fusion of low-quality multimodal data. |
|
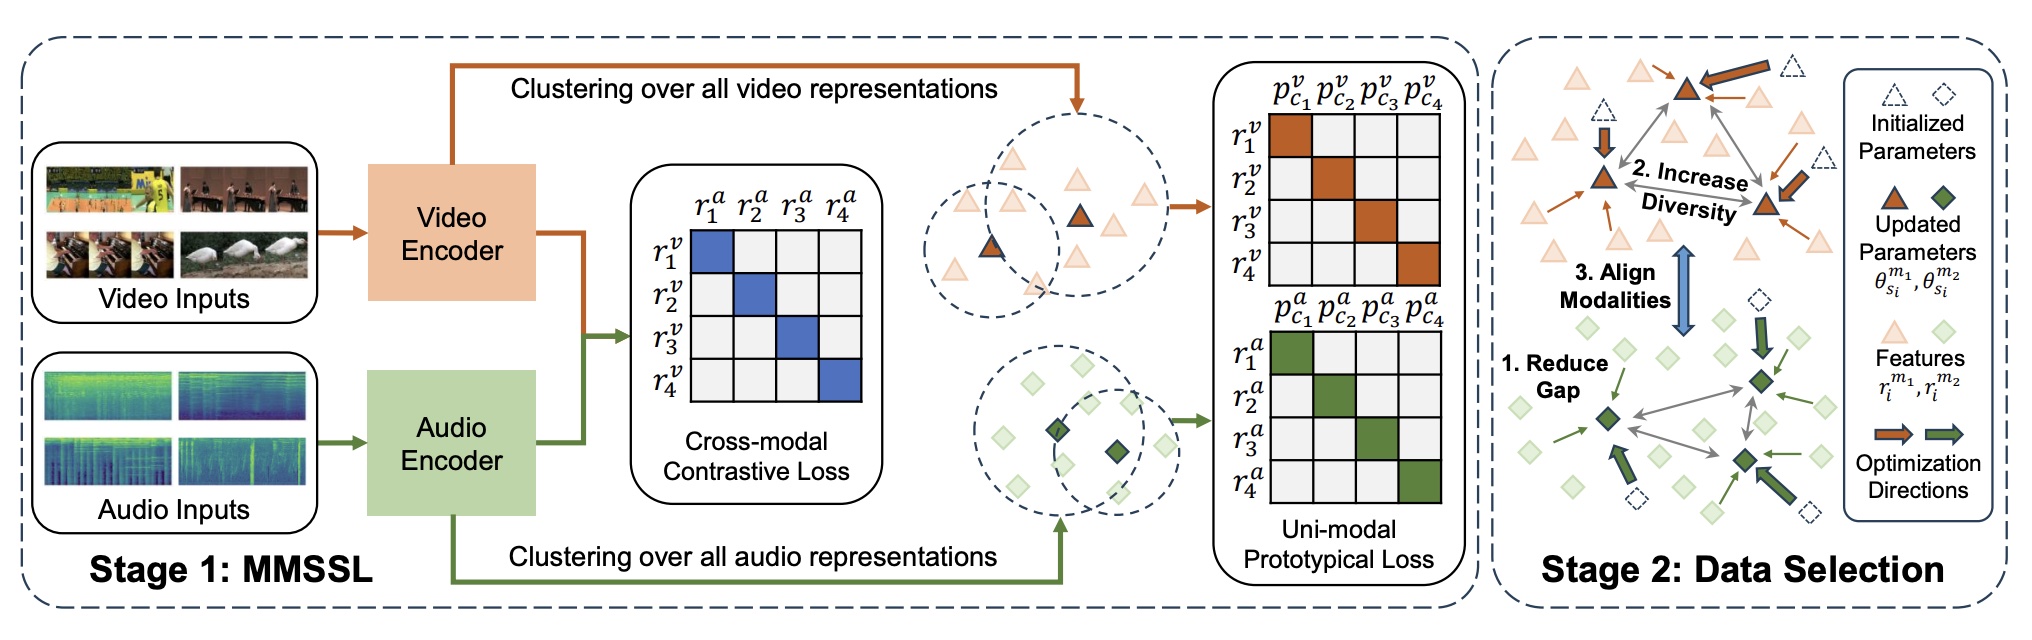
Meng Shen, Yake Wei, Jianxiong Yin, Deepu Rajan, Di Hu, Simon See ACM MM Asia, 2024 paper Improve the quality of selected multimodal data pairs in active learning. |
|
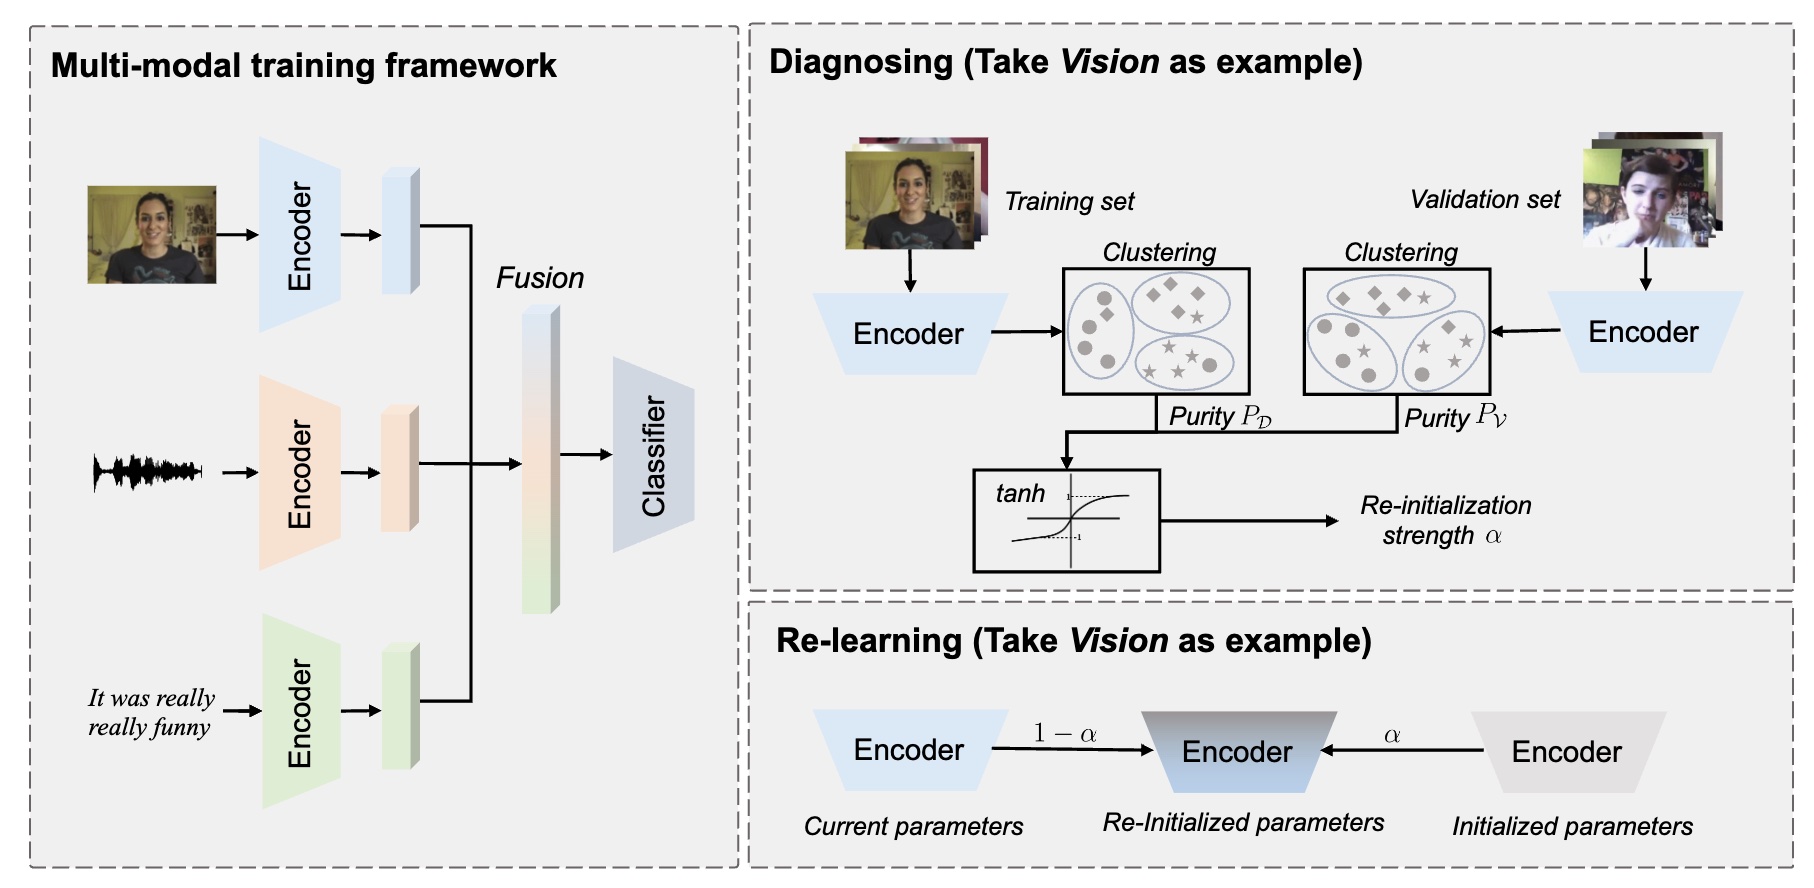
Yake Wei, Siwei Li, Ruoxuan Feng, Di Hu ECCV, 2024 arXiv / code Dynimically re-initialization to enhance both worse-/well-learnt modalities. |
|
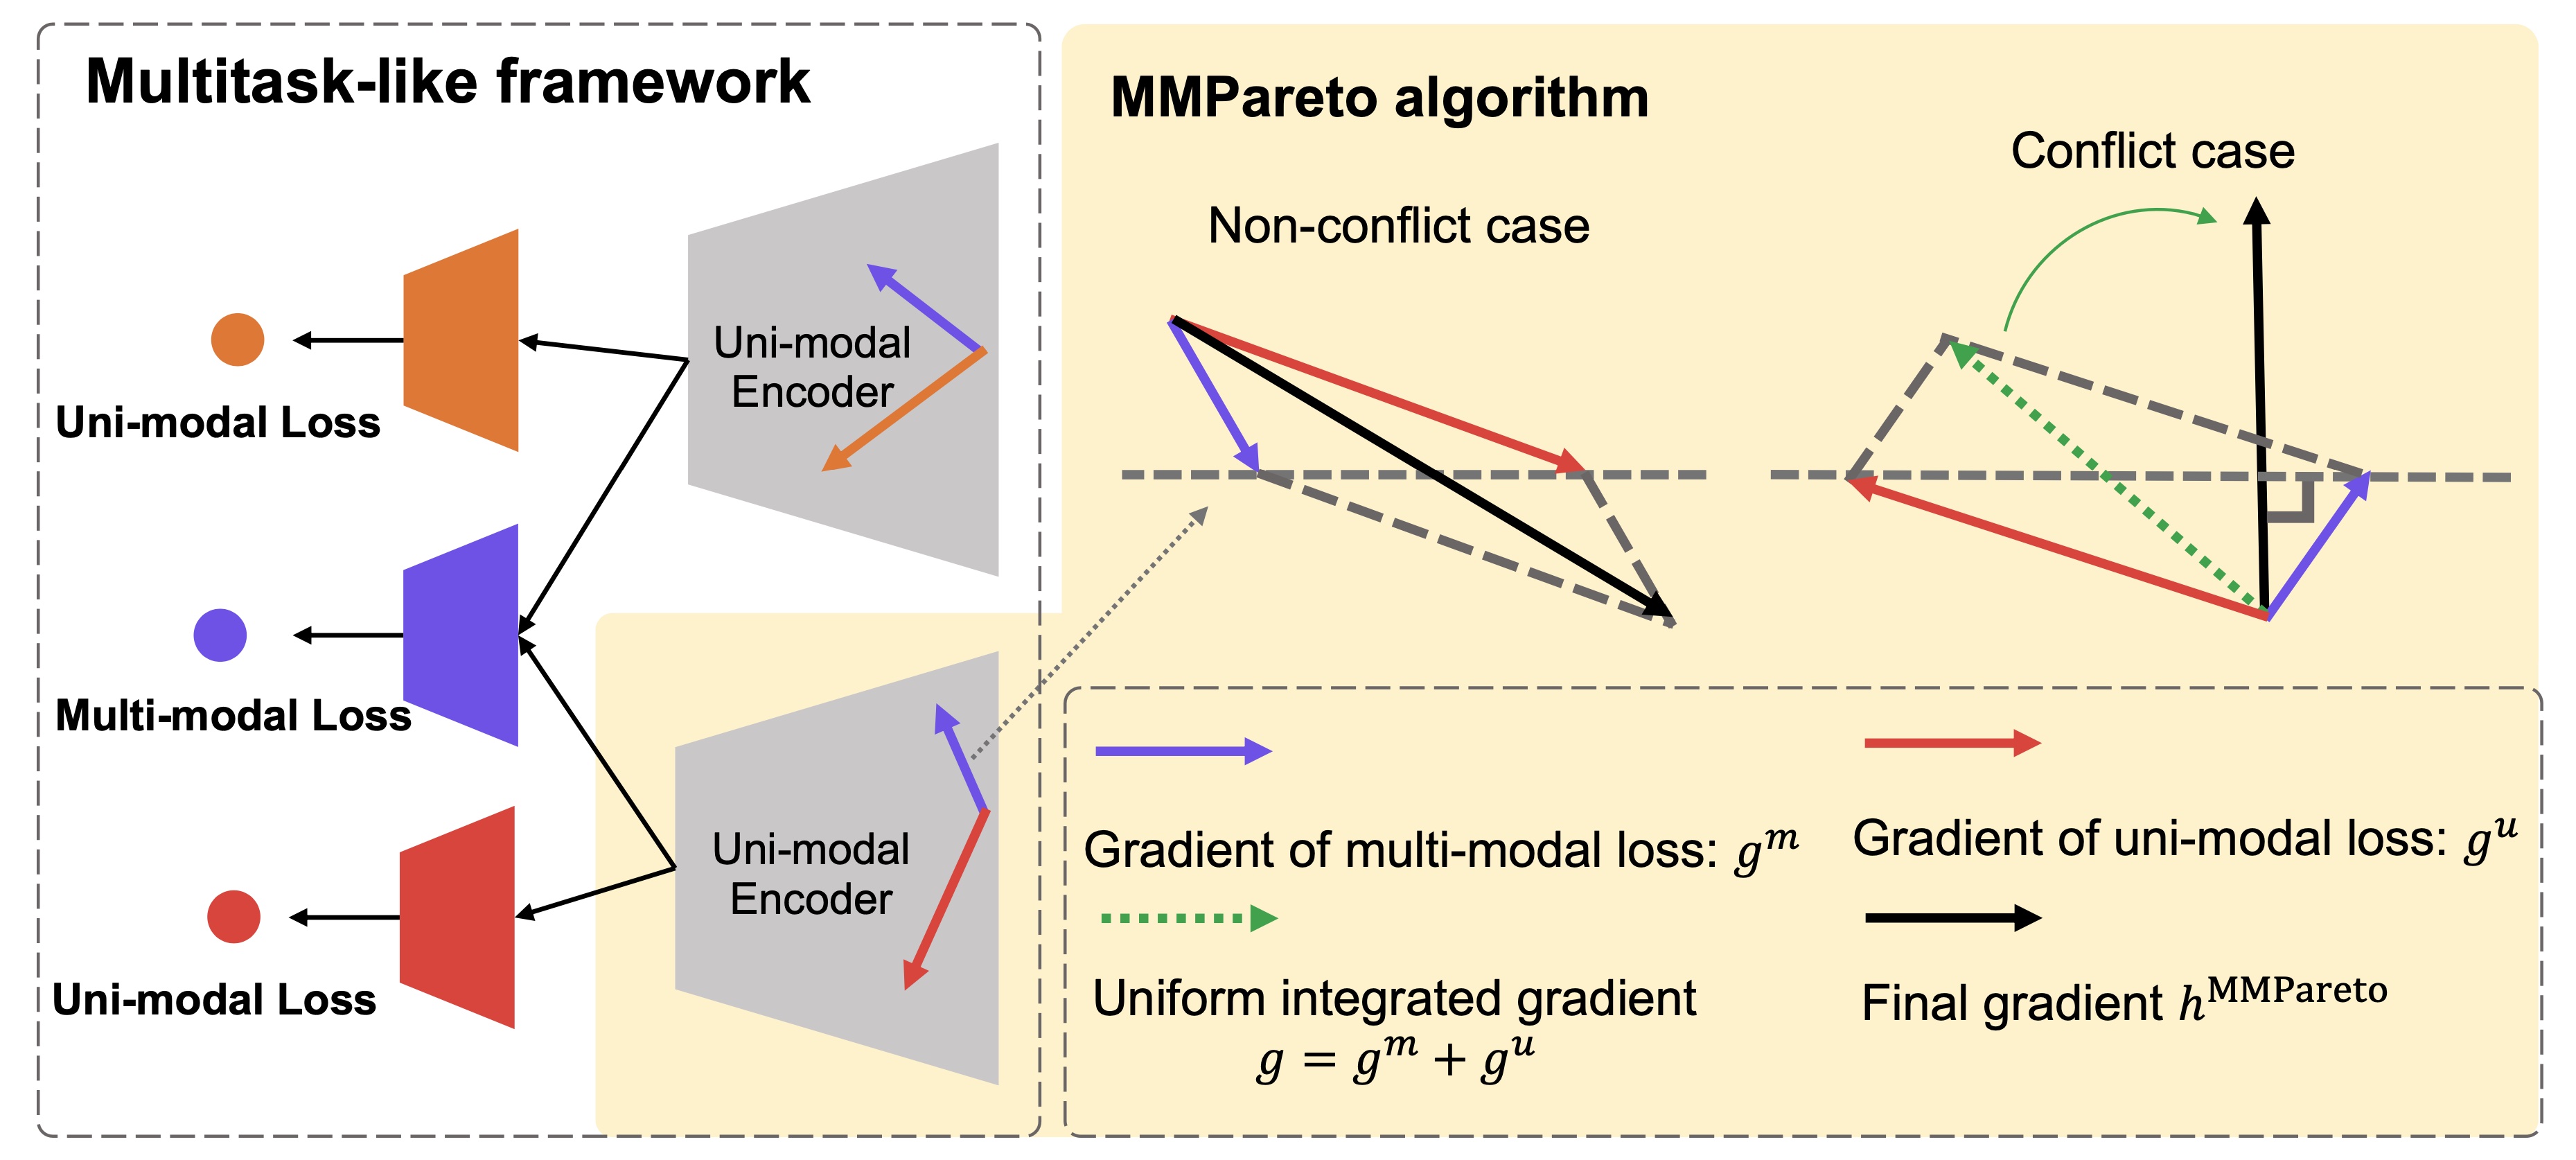
Yake Wei, Di Hu ICML, 2024 arXiv / code Solve conflicts between multimodal and unimodal gradients. |
|
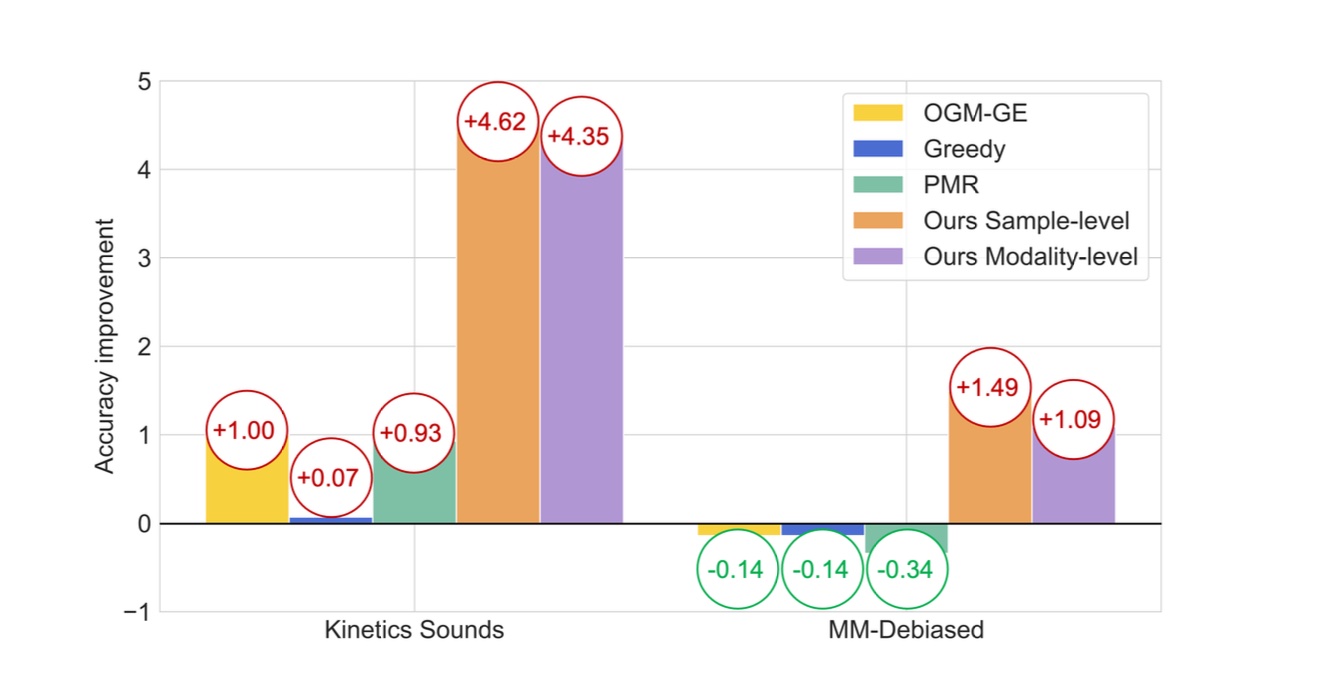
Yake Wei, Ruoxuan Feng, Zihe Wang, Di Hu CVPR, 2024 arXiv / code Observe and improve the fine-grained cooperation between modalities. |
|
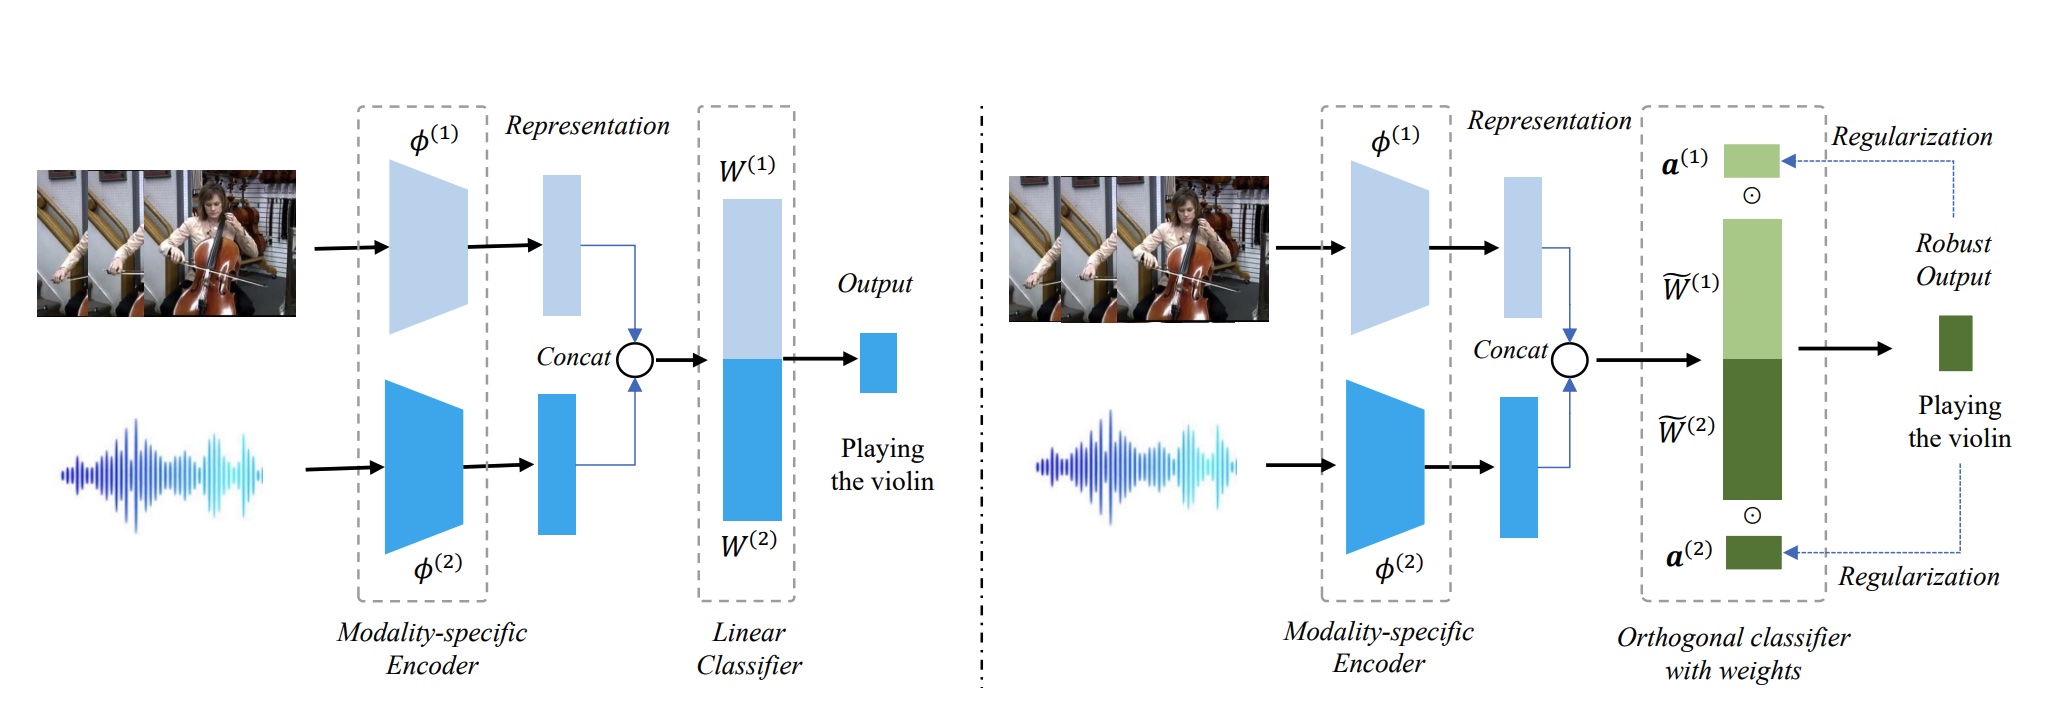
Zequn Yang, Yake Wei, Ce Liang, Di Hu ICLR, 2024 arXiv / code Analyze essential components for multimodal robustness and delve into the limitations imposed by modality preference. |
|
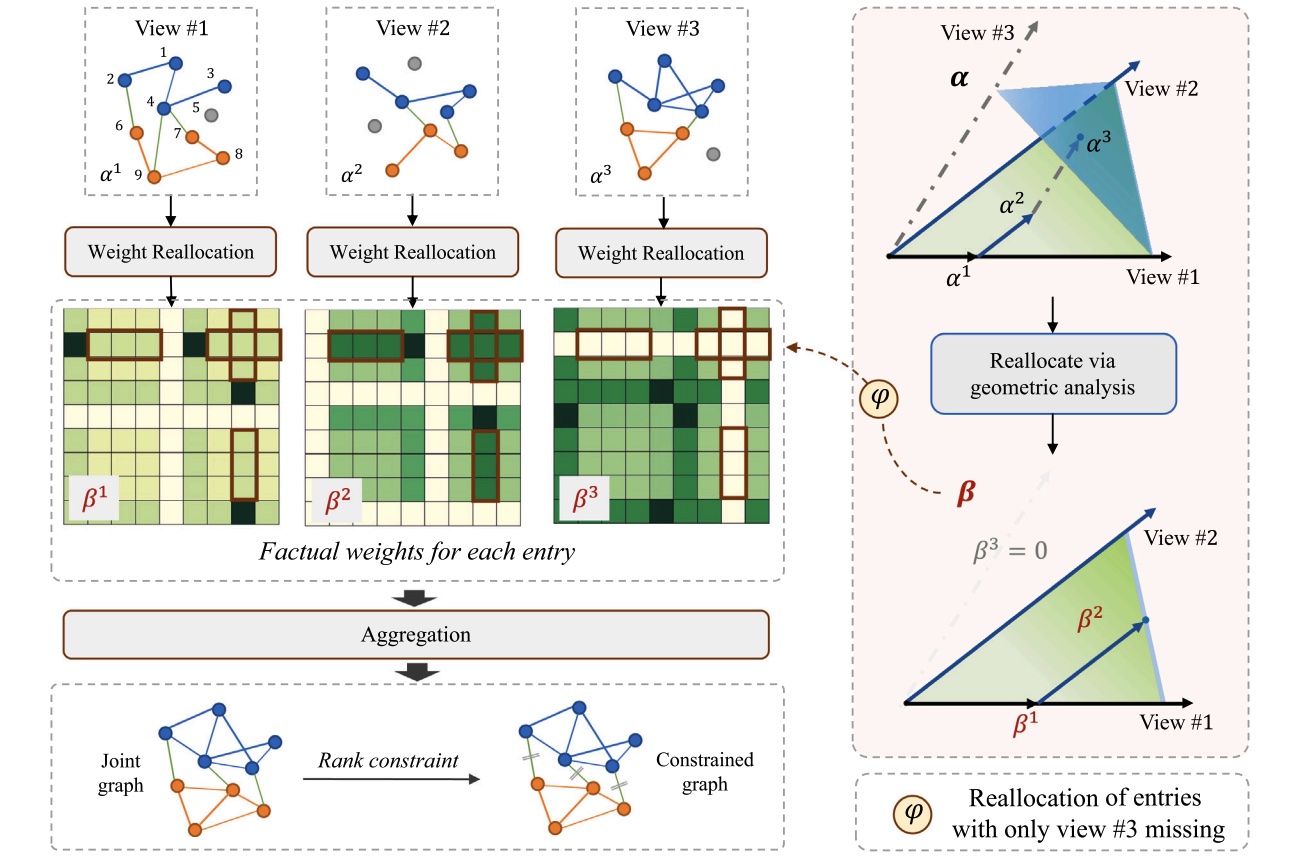
Zequn Yang, Han Zhang, Yake Wei, Zheng Wang, Feiping Nie, Di Hu Pattern Recognition, 2023 paper / code Conduct geometric analyses to mitigate missing views in weight aggregation. |
|
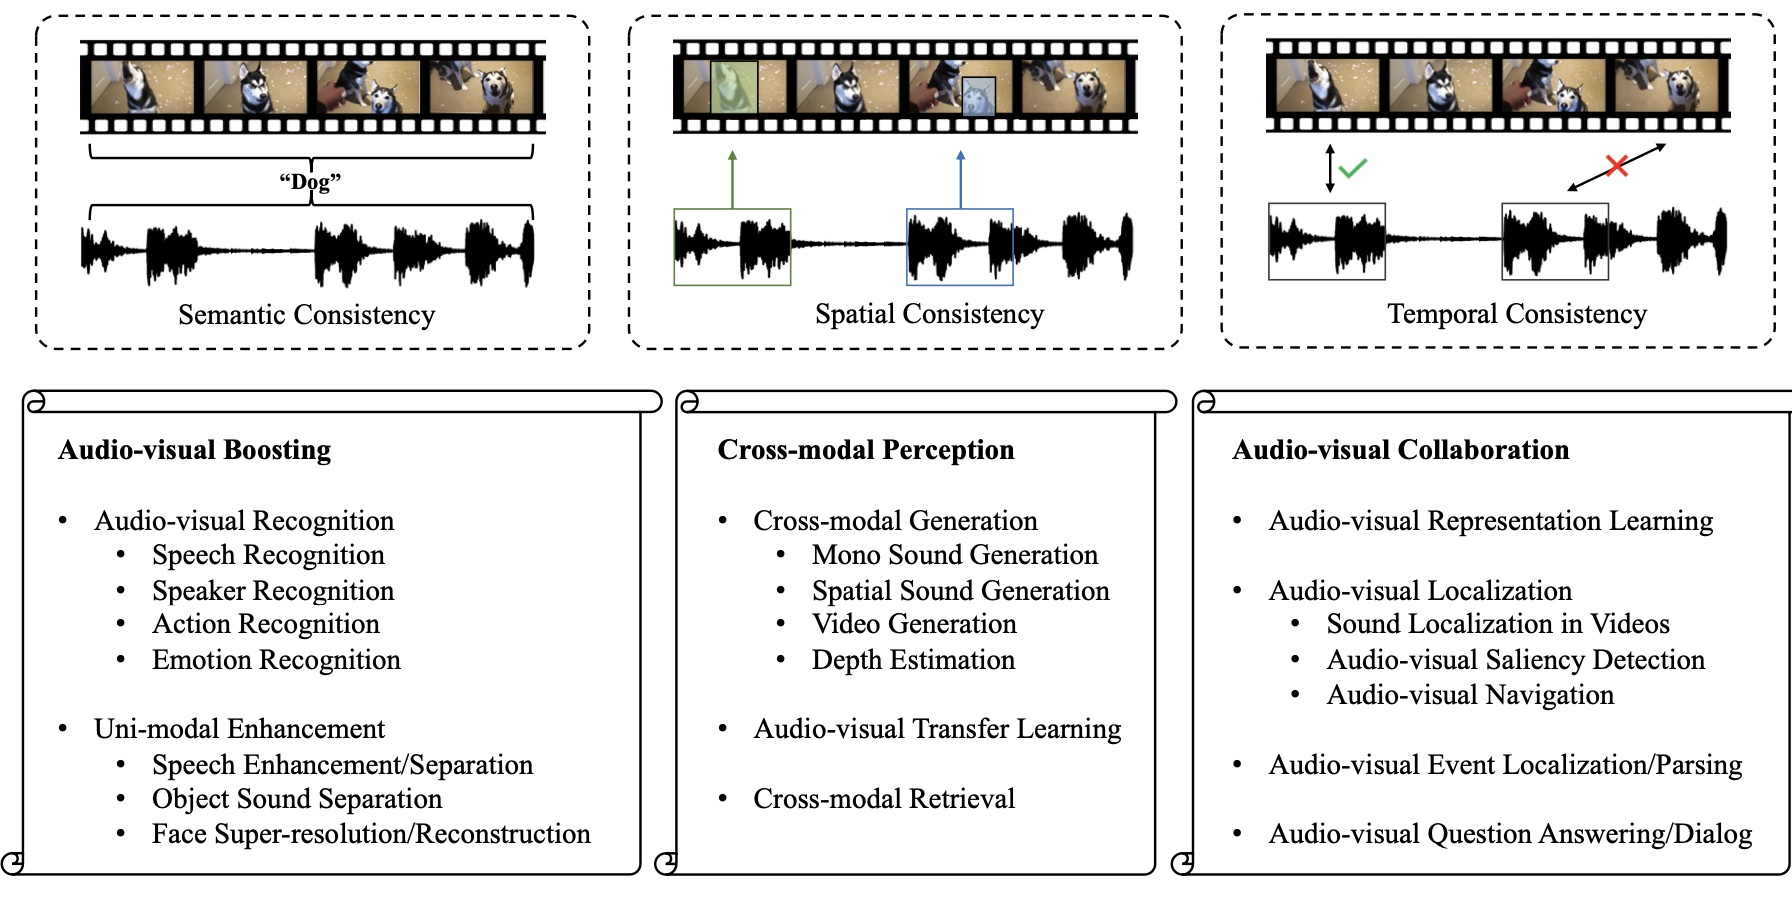
Yake Wei, Di Hu, Yapeng Tian, Xuelong Li Preprint, 2022 arXiv / website / awesome list A systematical survey about the audio-visual learning field. |
|
HIGHLIGHT
|
Xiaokang Peng*, Yake Wei*, Andong Deng, Dong Wang, Di Hu CVPR, 2022 (Oral Presentation) arXiv / code Alleviate imbalance in multimodal learning via dynamic gradient modulation. |
|
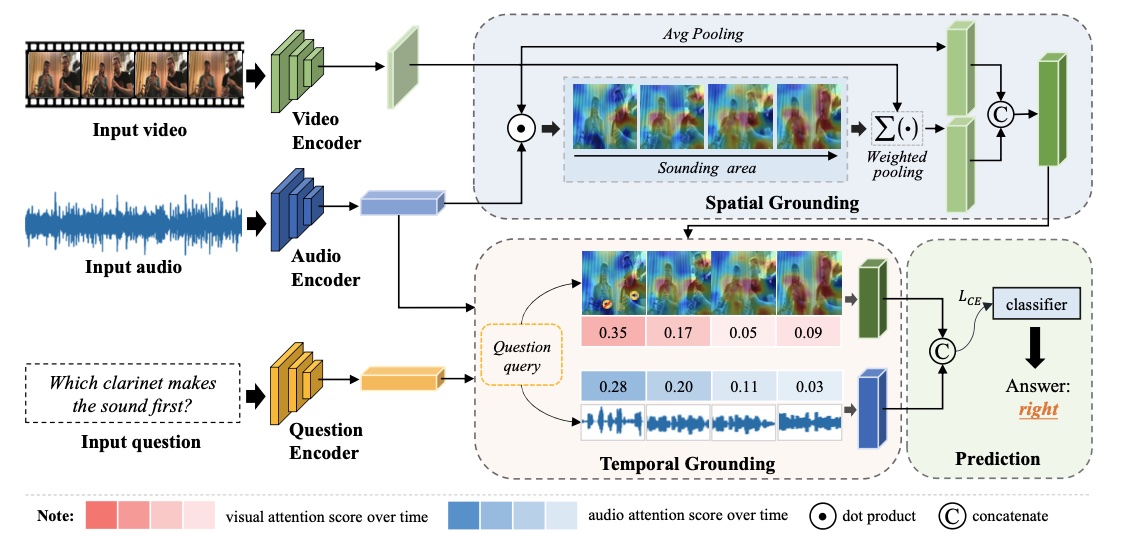
Guangyao Li*, Yake Wei*, Yapeng Tian*, Chenliang Xu, Ji-Rong Wen, Di Hu CVPR, 2022 (Oral Presentation) arXiv / project page Promote AVQA task and proposes MUSIC-AVQA dataset. |
|
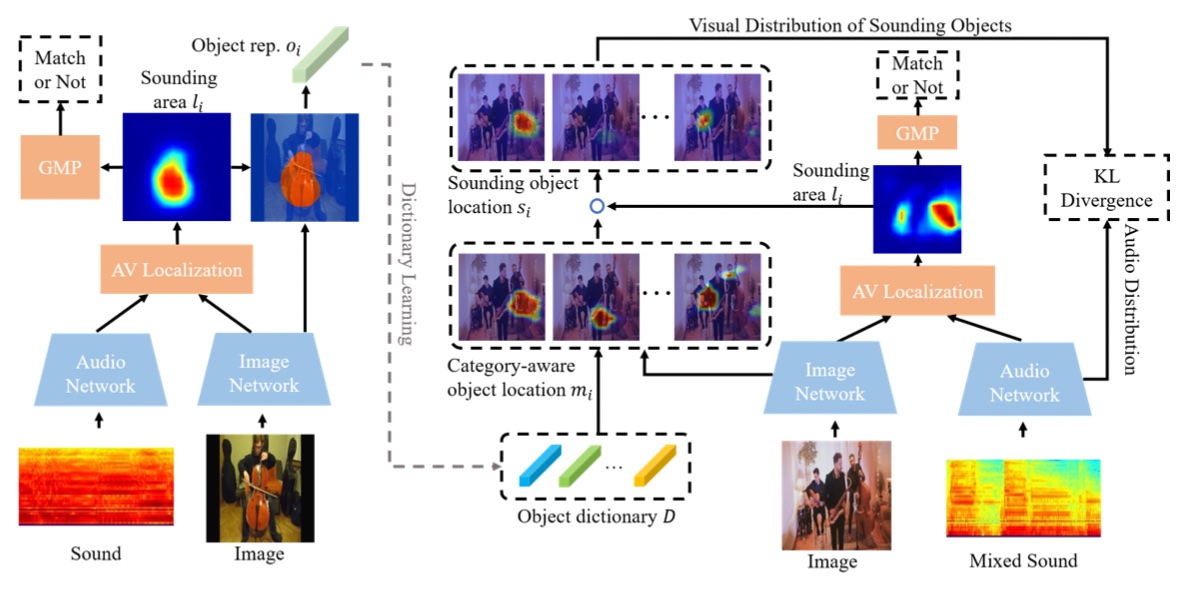
Di Hu, Yake Wei, Rui Qian, Weiyao Lin, Ruihua Song, Ji-Rong Wen T-PAMI, 2021 arXiv / project page Discriminative sounding objects localization. |
|
Organized Activities “Let's Talk about Balanced Multimodal Learning” 2025 — BML Workshop Invited Presentations
“Vibe Coding and Anything”
2026 — Fudan University, AI Agents for Nuclear Physics Workshop “Unified Audio-visual Scene Understanding” 2026 — CVPR, Sight and Sound Workshop
“Vibe Coding: From Autocomplete to CLI Agent”
2026 — TechBeat
“Balanced Multimodal Learning”
2025 — VALSE Student Workshop “Exploration of Audio-visual Scene Understanding and Multimodal Learning Mechanisms” 2022 — BAAI Conference Conference Oral Presentations “MokA: Multimodal Low-Rank Adaptation for MLLMs” 2025 — NeurIPS — Oral Presentation “Balanced Multimodal Learning via On-the-fly Gradient Modulation” 2022 — CVPR — Oral Presentation “Learning to Answer Questions in Dynamic Audio-Visual Scenarios” 2022 — CVPR — Oral Presentation |
|
Updated in September 2026
|